Fine-tune to change behaviour, use RAG to change knowledge
RAG and fine-tuning solve different failures: retrieval changes what a model knows, while fine-tuning changes how it behaves. Most ‘fine-tune it on our docs’ requests are retrieval problems.
Almost every enterprise AI conversation I sit in eventually produces the same sentence: "can we just fine-tune the model on our documents?" It sounds decisive — take the company's knowledge, bake it into the weights, done. Nine times out of ten it is the wrong instinct, and the reason is simple: fine-tuning does not do what people think it does.
Here is the decision, stated plainly before the nuance: fine-tune when you need to change how a model behaves; use retrieval when you need to change what it knows. If your problem is "the model does not know our data," that is a retrieval problem (RAG) — or often just a context problem — not a training problem. If your problem is "the model knows enough but will not answer in the shape, tone, or format we need, no matter how we prompt it," that is when fine-tuning earns its cost. Get that one distinction right and most of the "RAG vs fine-tuning" debate dissolves, because they were never solving the same thing.
What each one actually changes
rendering diagram…
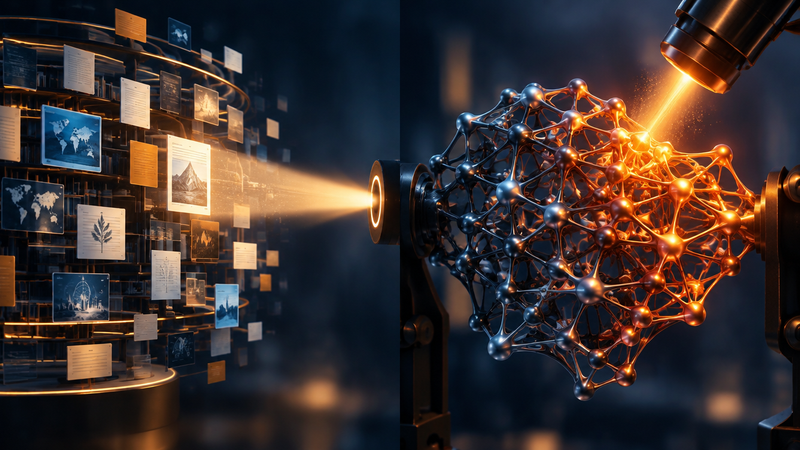
Retrieval-augmented generation (the original RAG paper framed it in 2020) leaves the model untouched and changes what sits in front of it. You fetch the relevant documents at question time and put them in the context window, so the model reasons over current, specific, citable material it never memorised. The knowledge lives outside the model and can change every hour.
Fine-tuning changes the weights. You are not teaching the model new facts so much as teaching it a new default behaviour — a house style, a strict output structure, a classification boundary, a way of refusing. The knowledge you fold in this way is frozen at training time and expensive to correct. That asymmetry is the whole game: retrieval is knowledge you can edit with a database write; fine-tuning is behaviour you buy with a training run.
When fine-tuning is the right call
Reach for fine-tuning when the failure is behavioural and prompting has genuinely hit a ceiling:
- Non-negotiable output shape. You need the same rigid JSON, the same tone, the same refusal pattern on every single call, and few-shot prompting still drifts. Fine-tuning makes the behaviour the default instead of a request.
- A narrow, high-volume task. A small fine-tuned model that does one classification or extraction job can be cheaper and faster at scale than a large model carrying a long instruction prompt on every request — this is where the model-economics argument for fine-tuning is real.
- Style the prompt cannot hold. Domain phrasing, a specific reasoning format, or a voice that a long system prompt only approximates.
Notice what is missing from that list: "so it knows our internal documents." That is the request I hear most, and it is the one fine-tuning serves worst.
When RAG — or just better context — wins
Use retrieval when the answer depends on knowledge, especially knowledge that moves:
- The facts change. Pricing, policies, inventory, this week's incident notes. Retraining to keep up is absurd; a retrieval index updates the moment the source does.
- You need traceability. Regulated and enterprise work usually has to show where an answer came from. RAG hands you citations; a fine-tuned weight cannot tell you which document it came from.
- You want cheap iteration. Fixing a bad answer means fixing a chunk or a retrieval query, not commissioning another training run and re-evaluating the whole model.
And before either: try the prompt. A surprising share of "we need RAG" turns out to be "we needed to actually put the relevant page in the context window and ask clearly."
The order I actually try them
This is judgement, not a law, but it has saved a lot of budget: prompt first, then retrieval, then fine-tuning — cheapest and most reversible first. Start by seeing how far a good prompt with the right context gets you. If the gap is missing or changing knowledge, add retrieval. Only when the gap is stubborn behaviour that survives good prompting and good retrieval do you spend on a training run. Teams that invert this order — fine-tuning on day one to "teach it our data" — routinely pay the most to solve the least, and then discover their frozen model is already out of date.
The honest test for any enterprise case is one question asked out loud: are we trying to change what the model knows, or how it behaves? Say the answer before you pick the tool.
FAQ
Can I use RAG and fine-tuning together?
Yes, and the strongest systems often do — but for different jobs. Fine-tune the model for reliable behaviour and output structure, and use retrieval to feed it current, citable knowledge at question time. They compose cleanly precisely because one touches weights and the other touches context.
Does a bigger context window make RAG unnecessary?
No. A larger window lets you stuff more in, but it does not decide what is relevant, keep it fresh, or cite it — that is retrieval's job. Bigger windows raise the ceiling for RAG; they do not replace it, and paying to fill a huge window with everything on every call is usually worse economics, not better.
Isn't fine-tuning cheaper at scale?
It can be, for a narrow high-volume task where a small tuned model replaces a large prompted one. But price the whole lifecycle, not just inference: data preparation, the training runs, evaluation, and the recurring cost of retraining every time the underlying knowledge or requirement shifts. For anything whose facts move, that recurring cost is where the "cheap at scale" story quietly falls apart.
What's in it for you
- A one-line filter for the next AI request: knowledge → retrieval; behaviour → fine-tuning. It settles most architecture arguments before they start.
- A spending order that fails cheap: prompt, then RAG, then fine-tune — so you only pay for a training run when the problem is genuinely behavioural.
- A way to catch the expensive mistake early: most "fine-tune it on our docs" asks are retrieval problems wearing a training-shaped costume.
Before you choose the tool, say whether you are changing what the model knows or how it behaves — the honest answer almost always picks it for you.