Router token share cannot count enterprise vendor switches
OpenRouter measures tokens in its platform; Ramp measures observed business spending. Their results can coexist without proving that enterprises have replaced incumbent providers.
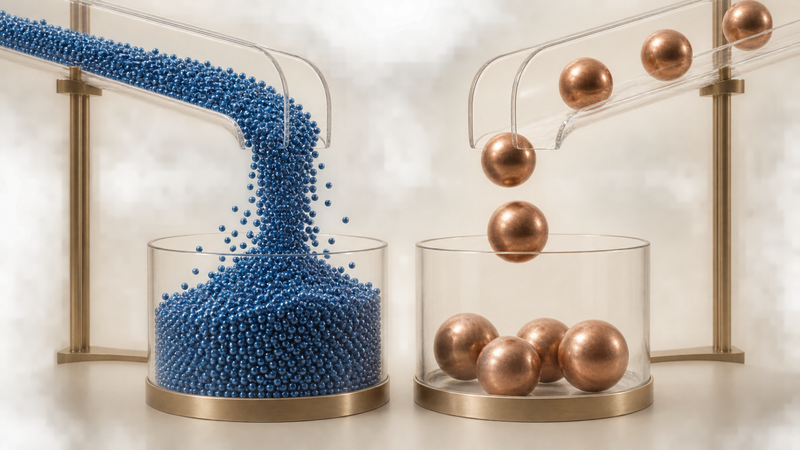
A model can win most of a company’s tokens and still fail to replace its main vendor.
That possibility is missing when router leaderboards become forecasts of enterprise market share. OpenRouter’s June analysis reports DeepSeek’s token share rising from 9% in January to 18% by early June. It is evidence about activity on OpenRouter, with the platform’s particular users and workloads.
Ramp’s July analysis uses a different lens. It reports that 5.8% of AI-spending businesses in its observed data used model-serving platforms in June. Among that group, 96.4% also used OpenAI or Anthropic. Ramp itself describes platform use as an imperfect proxy for open-source and Chinese-model adoption.
Those results are not contradictory. One measures token allocation in a router. The other measures observed vendor spending across a business population. The mistake is asking either chart to answer a question its denominator does not contain.
Tokens weight the busiest workloads
A token share is sensitive to how much text a workflow processes and produces. A long-running agent or a large batch job can account for far more tokens than many short, valuable interactions.
That weighting can be exactly right for infrastructure planning. It helps reveal where throughput and serving demand are moving. It is less useful for counting how many organizations standardized on a supplier, how much revenue changed hands or which workflow the buyer considers indispensable.
Price creates another separation. A lower-cost model can receive more tokens while accounting for a smaller share of spend. A higher-priced model can remain the preferred route for a limited set of difficult tasks. Neither observation requires the business to cancel the other provider.
My rule is to put the unit and population in the title of an adoption chart. “Token share among requests observed by this router” is less dramatic than “enterprise AI market share.” It is also a claim the data can support.
The cohort matters as much as the metric
Ramp reports that businesses using model-serving platforms spent a median $248 per employee on AI in June, roughly 23 times its median AI-spending business. That suggests an unusually intensive cohort in the observed data, rather than a representative sample of every enterprise buyer.
The difference does not invalidate the cohort. Intensive users can be early indicators of new workflows. It does limit how directly their behavior can be projected onto organizations with different budgets, skills and requirements.
The overlap with incumbent providers matters for the same reason. Continued spending does not prove that no workload moved. It does show why adding a model-serving platform cannot automatically be counted as replacing OpenAI or Anthropic.
A business might reduce one provider’s share, retain it for sensitive work and increase total AI spending at the same time. Vendor presence, spend share and workload allocation would each tell a different but compatible part of that story.
Build the comparison around a task
Imagine a hypothetical procurement review prompted by a router’s fast-growing model. I would take the model as a candidate for evaluation, not as a mandate to migrate.
Choose one existing workload and record its current quality threshold, cost, latency and data conditions. Evaluate the candidate under comparable conditions. If it passes, decide whether the move replaces an existing route, adds capacity or enables work we were not previously doing.
Those three outcomes should be recorded separately. A new bulk workflow can increase the candidate’s token share without taking any work away from the incumbent. A cheaper replacement can reduce spend even if total tokens remain unchanged.
rendering diagram…
This gives the enterprise a result it can use without making a claim about the entire market. The evaluation can support a routing change even when the market-share story remains unresolved.
Keep four measures from impersonating one another
I would distinguish accounts, spend, tokens and completed workloads in an internal adoption report. They may move together, but their divergence often explains the important change.
An account count describes breadth. Spend describes the bill under prevailing prices. Tokens describe processing volume. Completed workloads describe useful output only if the completion criteria are defined and checked. None should silently inherit the meaning of the others.
The report also needs a stable time window. A new model’s launch surge should not be compared with a long-run annual share without showing the mismatch. Free promotions, changes in routing defaults and newly supported workloads can all affect observed activity and deserve investigation before a causal conclusion.
I have not reproduced either provider’s underlying dataset. The published summaries are useful evidence within their stated scope. They do not supply an enterprise-only denominator for every router request or reveal the precise tasks behind every expense.
The practical response is neither dismissal nor extrapolation. Use the signal to decide what to test, then use the test to decide what to deploy.
A router leaderboard can nominate a model; only matched workload evidence can justify your vendor switch.